

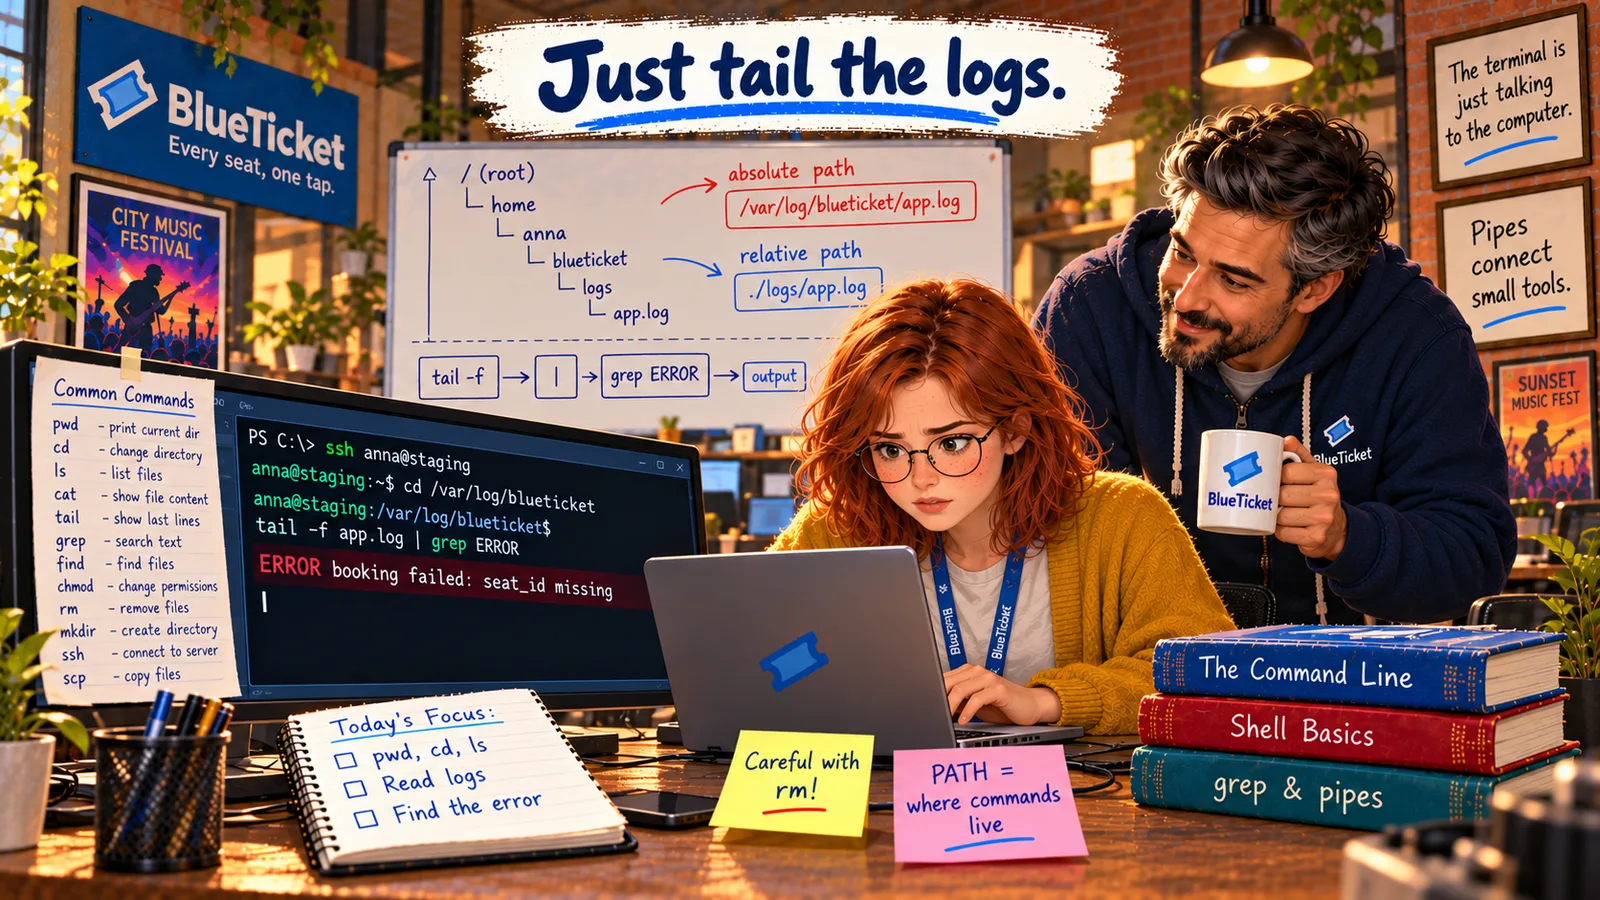
In this chapter
We'll learn to connect commands with pipes, save output to files with redirection, and understand environment variables and PATH — finishing the bug hunt Anna started and explaining Act 04's "command not found".
The Problem in Real Life
Anna has her clue: the error only happens for bookings from the mobile app. The mobile team wants proof — a file with today's failed bookings, and the live log lines when it happens.
"You already used a pipe without knowing it," John says, pointing at the | in her last command. "That little line is one of the best ideas in computing. Let me show you why."
Small tools that each do one thing — joined together, they can do almost anything.
John
One Big Program vs. Small Commands Joined Together
Commands can be chained
The output of one command can become the input of the next.
Output can go to a file
Instead of printing to the screen, a command's result can be saved — or added to a file.
How the shell finds programs
When you type node, the shell searches a list of folders. That list is called PATH.
Pipes, Redirection, Environment Variables and PATH
Every command has an input and an output. By default, input comes from your keyboard and output goes to your screen. The shell lets you change both.
- Pipe
|— sends the output of one command straight into the next command as its input.tail -f app.log | grep ERRORmeans: "follow the log, and pass every new line to grep, which only shows the error lines." You can chain many:grep ERROR app.log | grep mobile | tail -n 5. - Redirect output
>— saves a command's output to a file instead of the screen. If the file exists, it is replaced.grep ERROR app.log > errors.txt. - Append
>>— adds the output to the end of a file, keeping what's already there.echo "checked at 11:00" >> notes.txt. - Redirect input
<— gives a command a file as its input instead of the keyboard. Less common in daily use. - Errors are separate: Programs print normal output and error messages on two different channels.
>only catches normal output;2>catches errors:npm run build 2> build-errors.txt.
| Symbol | Name | Example | What it does |
|---|---|---|---|
| | | Pipe | grep ERROR app.log | tail -n 5 | Output of the first becomes input of the second |
| > | Redirect (replace) | grep ERROR app.log > errors.txt | Saves output to a file, replacing it |
| >> | Redirect (append) | date >> notes.txt | Adds output to the end of a file |
| < | Redirect input | wc -l < app.log | Uses a file as the command's input |
| 2> | Redirect errors | npm run build 2> errors.txt | Saves only error messages |
| Variable | Example value | Meaning |
|---|---|---|
| HOME | /home/anna | Your home folder |
| USER | anna | The logged-in user |
| PWD | /var/log/blueticket | The current directory |
| PATH | /usr/local/bin:/usr/bin:/bin | Folders searched for commands |
| NODE_ENV | production | Tells a Node.js app which mode to run in |
How the bug hunt command works
tail -f app.log
every new log line, as it's written
grep ERROR
keeps only the error lines
grep -i mobile
keeps only errors from the mobile app
Screen
or > a file, to save it
# Save today's failed bookings for the mobile teamgrep "booking failed" app-today.log > failed-bookings.txtwc -l failed-bookings.txt # wc -l counts lines# 37 failed-bookings.txt# Watch only mobile errors, livetail -f /var/log/blueticket/app.log | grep ERROR | grep -i mobile# Where does the shell find node?echo $PATH# /usr/local/bin:/usr/bin:/binwhich node# /usr/local/bin/node
Environment variables: The shell keeps a set of named settings called environment variables, and every program you start gets a copy. They hold things like your user name (USER), your home folder (HOME), and app settings like NODE_ENV=production or the database address. You read one with $ in front: echo $HOME. You set one for the current session with export NAME=value. In Act 16, Anna will use them to keep passwords out of code.
PATH is the most important environment variable of all. It's a list of folders, separated by : (or ; on Windows). When you type a command like node, the shell looks in each PATH folder, in order, for a program with that name, and runs the first one it finds. which node shows you where it found it.
And that finally explains Act 04's mystery. node: command not found meant the shell searched every folder in PATH and found no program called node. Installing Node.js put it in a folder that's on the PATH — and the error went away. When a freshly installed tool still says "not found," the usual fix is to open a new terminal (so it reads the updated PATH) or add the tool's folder to PATH.
Back to the bug: Anna puts it all together. She saves today's failed bookings to a file for the mobile team, counts them, and watches the live log filtered to errors. Then she notices one more detail in the full log line: the mobile app sends a field called seatId, but the server expects seat_id. A small naming mismatch after last week's mobile update. She sends the file and the finding to the mobile team. An hour later, their fix is on staging, and the error count stays at zero.
Key Takeaway
A pipe | feeds one command's output into the next; > saves output to a file (replacing it), >> appends, and 2> captures errors. Environment variables are named settings every program inherits, and PATH is the list of folders the shell searches when you type a command — which is why "command not found" means "not in any PATH folder."
Why This Matters
Pipes and redirection turn a handful of small commands into a powerful toolkit — this is how engineers answer questions about logs, data and systems in seconds. Environment variables and PATH are behind countless "it works on my machine" problems, and they come back in Act 16 (settings and secrets) and Act 19 (deploying with the right configuration). The Linux Fundamentals course takes all of this much further.
In one week, Anna went from "I don't know how to get there without a mouse" to finding a real bug on a server using only the terminal. John has one last test before Act 07: a log file and a question, and nothing but a prompt.