

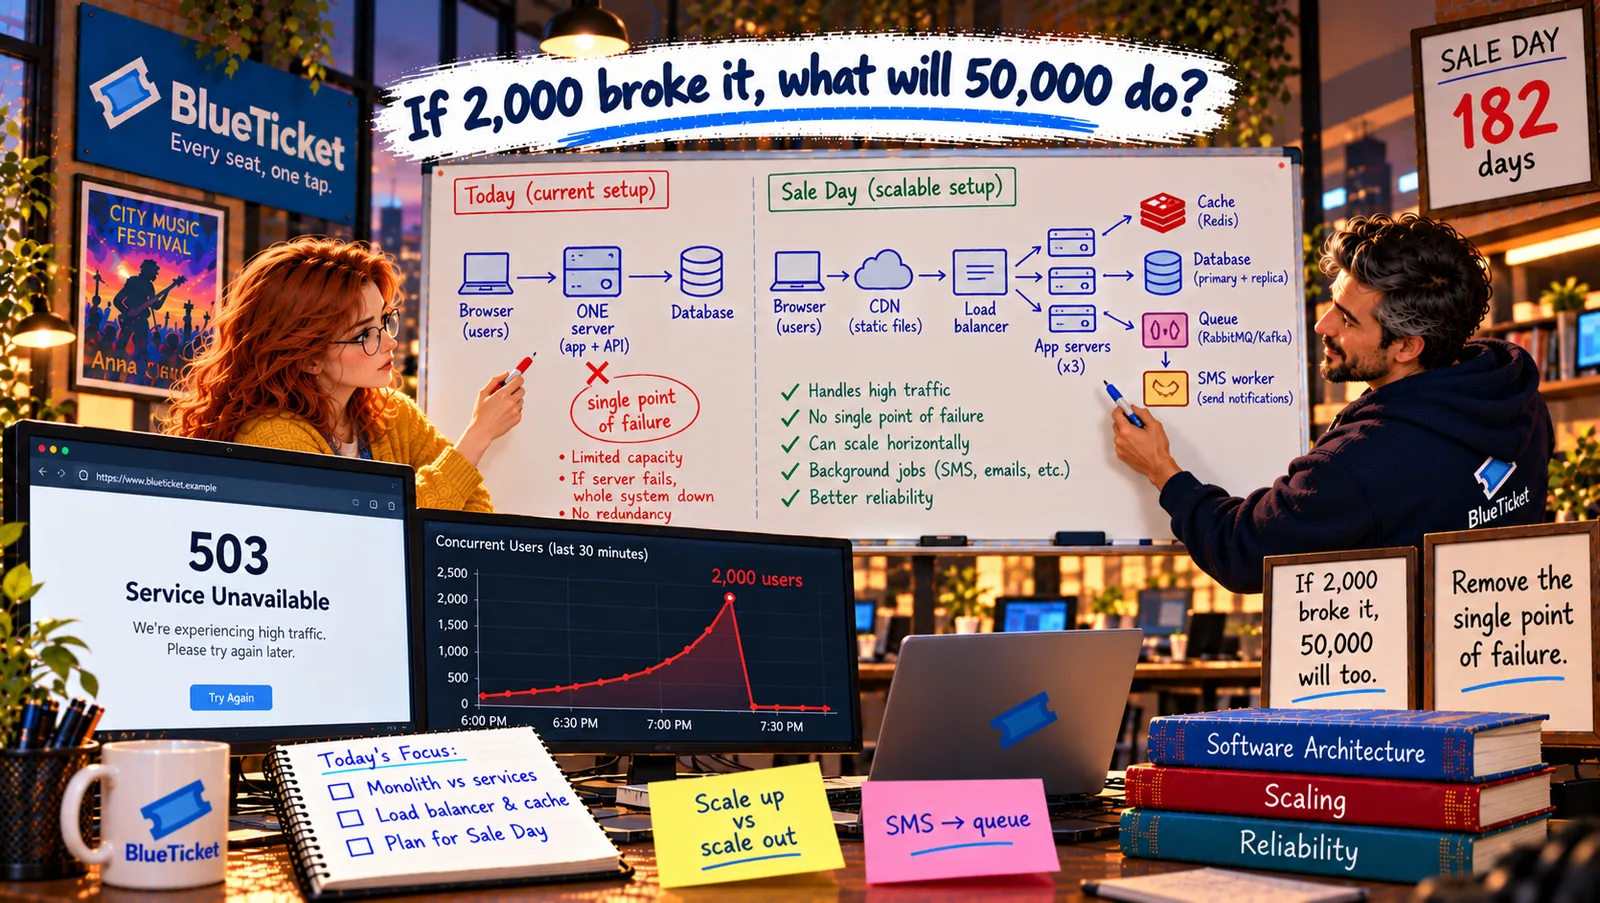
In this chapter
We'll learn how systems stay up when parts fail — availability and the "nines", reliability, fault tolerance and redundancy (an airplane with two engines), and the single point of failure (one bridge into town) — then hunt every one of them in BlueTicket's diagram.
The Problem in Real Life
John puts his finger on the load balancer in Anna's Sale Day diagram. "One box. If it dies at 10:00 on Sale Day, what happens?" She follows the arrows. Every fan's request goes through it. "Then... nobody gets in. Not even to the four healthy app servers behind it."
He moves his finger to PostgreSQL. "And this?" She doesn't need to answer. "Four app servers make us fast," he says. "They don't make us safe. For that, we need a different way of looking at the diagram."
Look at every box and ask one question: if this disappears right now, what stops working?
John
"It Works" vs. "It Keeps Working When Something Breaks"
Everything fails eventually
Servers crash, disks die, networks drop. The question isn't if, but what happens when.
Some parts are single doors
If the only path goes through one box, that box can take everything down.
Uptime has a number
"Always up" isn't a plan. Availability is measured, promised and designed for.
High Availability, Reliability and Fault Tolerance
The airplane analogy: a passenger plane has two engines, even though it can fly on one. Hospitals have backup generators. Cars carry a spare tyre. Nobody expects these parts to fail today — but everyone knows something will fail eventually, so the important parts have a spare. Systems that must stay up are designed the same way.
- Availability — how much of the time it's up: availability is the share of time a system is working and reachable, usually written as a percentage with "nines": 99% ("two nines") sounds great, but means about 3.7 days of downtime a year. 99.9% ("three nines") is about 8.8 hours a year. 99.99% is about 53 minutes a year. Each extra nine is much harder and more expensive. High availability (HA) means designing a system to reach a high number like these.
- Reliability — does it work correctly over time? Reliability is how consistently a system does the right thing, without failing or giving wrong results. A system can be available but unreliable — up all day, but double-booking seats (Act 13). Both matter: fans need the site to be up and right.
- Fault tolerance — keep flying on one engine: fault tolerance is a system's ability to keep working when part of it fails. With four app servers behind a load balancer, one can crash and fans won't notice — the system tolerates that fault. It's achieved with redundancy: having more than one of each important part, so a spare can take over.
- Single point of failure (SPOF) — the one bridge into town: if a town has only one bridge and it collapses, nobody can get in or out, however good the roads on either side are. A single point of failure is any one part whose failure stops the whole system. Finding and removing SPOFs is one of the most important habits in architecture.
| Availability | Downtime per year | Downtime per month |
|---|---|---|
| 99% (two nines) | about 3.7 days | about 7.3 hours |
| 99.9% (three nines) | about 8.8 hours | about 44 minutes |
| 99.99% (four nines) | about 53 minutes | about 4.4 minutes |
| 99.999% (five nines) | about 5 minutes | about 26 seconds |
| Box | If it disappears... | SPOF? | Fix |
|---|---|---|---|
| Load balancer (one) | Nobody gets in | Yes | Two, with automatic takeover |
| App servers (four) | Others carry the load | No | Already redundant |
| PostgreSQL (one) | No bookings at all | Yes | Standby replica + failover + backups |
| Redis (one) | Everyone logged out, cache gone | Yes | Redis replica |
| Queue | SMS paused, bookings fine | Partial | Replica; messages wait safely |
| SMS provider | Texts delayed | No (degrades) | Queue holds messages until it's back |
| Term | Question it answers | Example |
|---|---|---|
| Availability | Is it up? | The site answers 99.9% of the time |
| Reliability | Does it work correctly over time? | No seat is ever sold twice |
| Fault tolerance | Does it keep working when a part fails? | One app server dies; fans don't notice |
Removing single points of failure
Load balancer ×2
one takes over if the other fails
App servers ×4
one can crash, others carry on
PostgreSQL main + standby
automatic failover, plus backups
Redis main + replica
sessions survive
Queue + SMS workers
if SMS fails, messages wait — graceful degradation
Anna's SPOF hunt: she goes through the Sale Day diagram box by box, asking "if this disappears, what stops?" The load balancer: everything — SPOF. Fix: two load balancers, with the second taking over automatically if the first fails (cloud providers offer this built in). The app servers: nothing — there are four, so it's not a SPOF. PostgreSQL: all bookings stop — SPOF. Fix: a standby replica kept up to date that can be promoted to main within seconds (failover), plus regular backups. Redis: everyone is logged out and the cache disappears — SPOF for sessions. Fix: a Redis replica too. The queue: SMS messages pause, but bookings still work — a partial failure, acceptable for an hour, but worth a replica. The SMS provider: messages are delayed — the queue simply holds them until it's back.
Failing safely, not just failing less: some failures can't be prevented, so a good system decides what happens when they occur. If the SMS company is down, bookings continue and texts are sent later. If the cache is empty, requests go to the database, a bit slower. This is called graceful degradation: losing a feature, not the whole system.
John adds one more box to the diagram, far to the side: a second data centre (availability zone). "Even a whole building can lose power," he says. "That's Act 20." Samantha looks at the finished diagram and asks the only question she cares about: "So if one thing breaks on Sale Day, we keep selling?" For the first time, Anna can answer: "Yes. If one thing breaks."
Key Takeaway
Availability is the share of time a system is up (99.9% ≈ 8.8 hours of downtime a year); reliability is whether it works correctly over time. Fault tolerance — keeping going when a part fails — comes from redundancy, like a plane's second engine. A single point of failure is one part whose loss stops everything, like the only bridge into town: find every one, add a spare, and design failures to degrade gracefully.
Why This Matters
On Sale Day, ten minutes of downtime at 10:00 AM would cost BlueTicket its biggest client. Every serious system is designed around the assumption that parts will fail — and the SPOF question ("if this disappears, what stops?") is something you can ask about any system, from a website to a payment flow to a team that depends on one person who knows everything.
Anna's diagram has grown from one box to more than a dozen, with arrows everywhere. John tells her that reading diagrams like this — quickly, and asking the right questions — is a skill on its own. It's the last one in this Act.