

In this chapter
We'll meet workload analysis as a real discipline, and its first four questions — data shape, access patterns, read/write ratio, relationship complexity, and search requirements — applied to GreenMart's own next expansion.
The Problem in Real Life
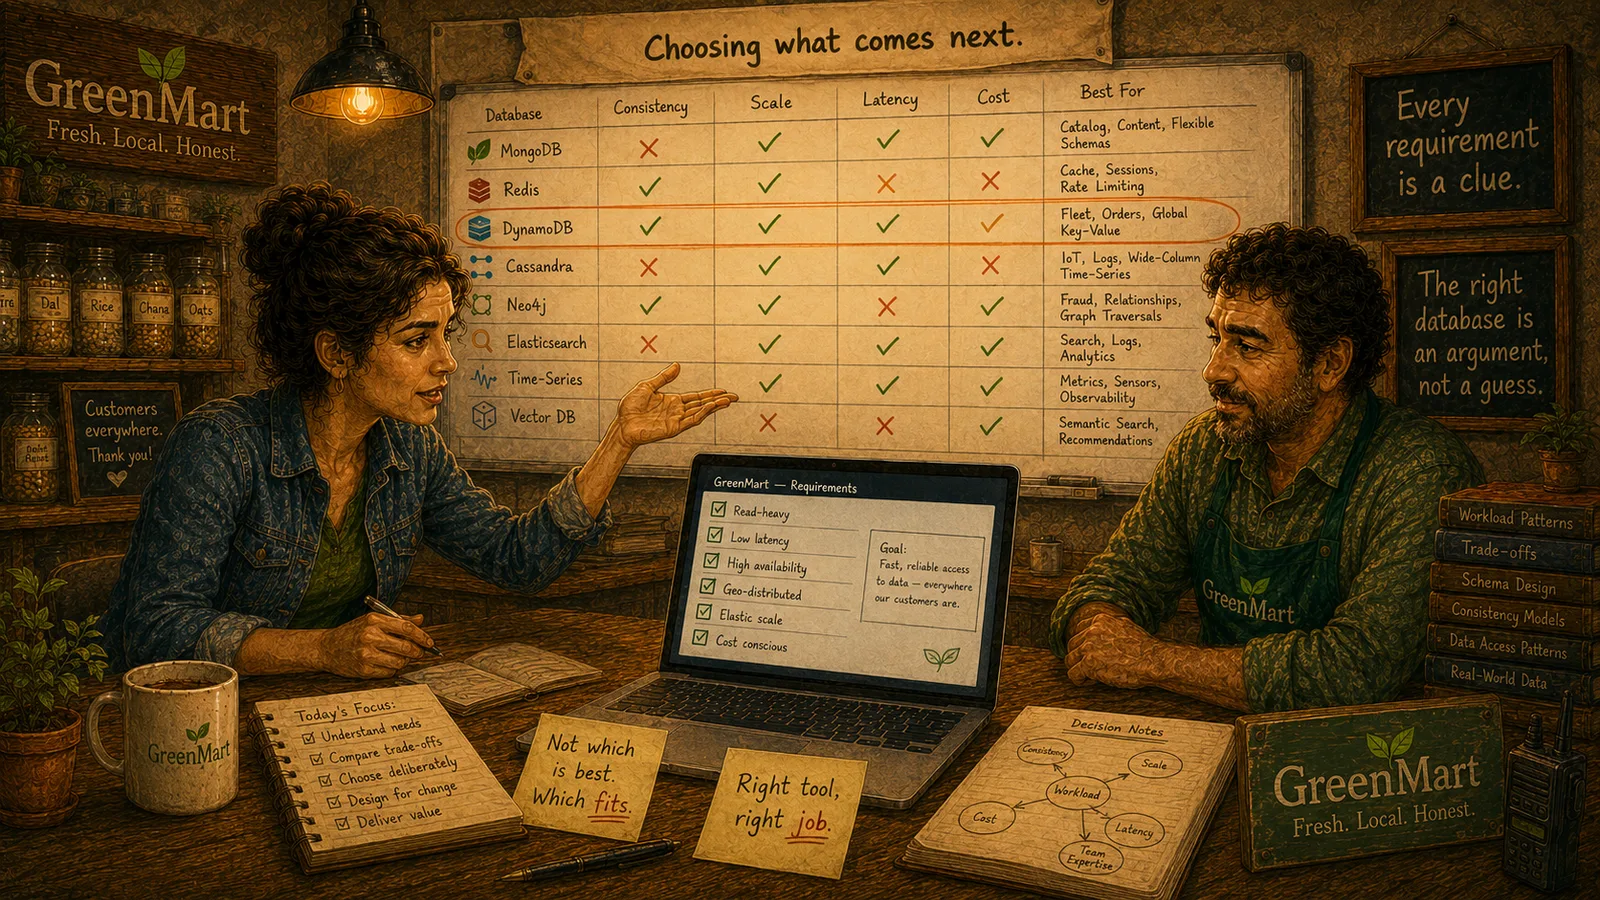
Thirteen Acts in, and Mike finally asks the question this whole course has been quietly building toward: GreenMart's next expansion needs a home for fleet and order data that works the same way in every country it operates in. Which database?
Sarah doesn't reach for a name. She reaches for a notebook.
So which one do we use this time?
Mike
Picking a Name vs. Reading the Requirements
Read the workload before naming a database
Workload analysis means writing down the real, specific shape of the problem before any technology gets chosen.
Data shape and access patterns
How the data is naturally structured, and how it actually gets read and written — two separate, equally real questions.
Workload Analysis & Data Shape
Every earlier Act in this course started with a specific technology and showed what it was good at. This one starts the other way around: a real, unlabeled requirement, and the discipline to read it correctly before a single database name gets mentioned.
- Workload analysis is that discipline, named directly: before choosing anything, write down, precisely, what the actual workload looks like — not what sounds impressive, not what GreenMart used last time, just the real, specific shape of the problem. Every concept in this chapter, and the four after it, is one specific question workload analysis asks.
- On the shape of the data itself. Data shape asks whether GreenMart's new fleet-and-order data is naturally flat rows, deeply nested documents, tightly connected relationships, or something else entirely — the same question Act 2 answered for MongoDB's documents and Act 6 answered for graph's relationships, now asked fresh, before any answer is assumed.
- On how the data actually gets touched. Access patterns — the specific, concrete ways data gets read and written, the same discipline Act 4's single-table design was built on — matter more than the data's shape alone. Read/write ratio is one specific access pattern worth naming on its own: is this workload read-heavy (many lookups per write, like a product catalog) or write-heavy (constant updates, like live fleet locations)? The two need genuinely different trade-offs, the same lesson Act 3's Redis and Act 5's Cassandra each taught from a different angle.
- On what else the data connects to. Relationship complexity asks how tangled the connections between records actually are — a flat list of independent orders is simple; a fraud-style web of shared devices and referrals, Act 6's own territory, is not. Search requirements asks a separate, honest question: does GreenMart need to look records up by a known key, or genuinely search across fuzzy, ranked, full-text content, Act 7's own distinct job?
None of this names a database yet, on purpose. GreenMart's fleet-and-order requirement, on this first pass: mostly flat records (low relationship complexity), a real mix of reads and writes, looked up by known keys rather than searched, with no deep nested structure. That's real information, even before scale, guarantees, or cost enter the picture — which is exactly what the next four chapters add, one category at a time.
Key Takeaway
A database gets chosen well by reading the workload first and the technology second — every earlier Act taught one database's strengths in isolation; this Act teaches the discipline of describing the problem precisely enough that the right database becomes obvious, not guessed.
Why This Matters
"Which database should we use?" asked without a precise workload in hand is the same mistake this course's very first Act warned against: reaching for a familiar tool instead of the one the actual problem calls for. Workload analysis is what turns that question answerable.
GreenMart now has the first real facts about the fleet-and-order requirement: its data shape, its access patterns, its read/write balance, its relationship complexity, and its search needs. The next chapter adds a different, equally real category: what GreenMart is actually promising about consistency, availability, and speed.