

In this chapter
We'll meet Cassandra's ring architecture — nodes, token ranges, and the partitioner that maps a partition key to a physical node — plus gossip (how nodes learn cluster state without a central authority) and coordinator nodes (a temporary role any node can pick up per request).
The Problem in Real Life
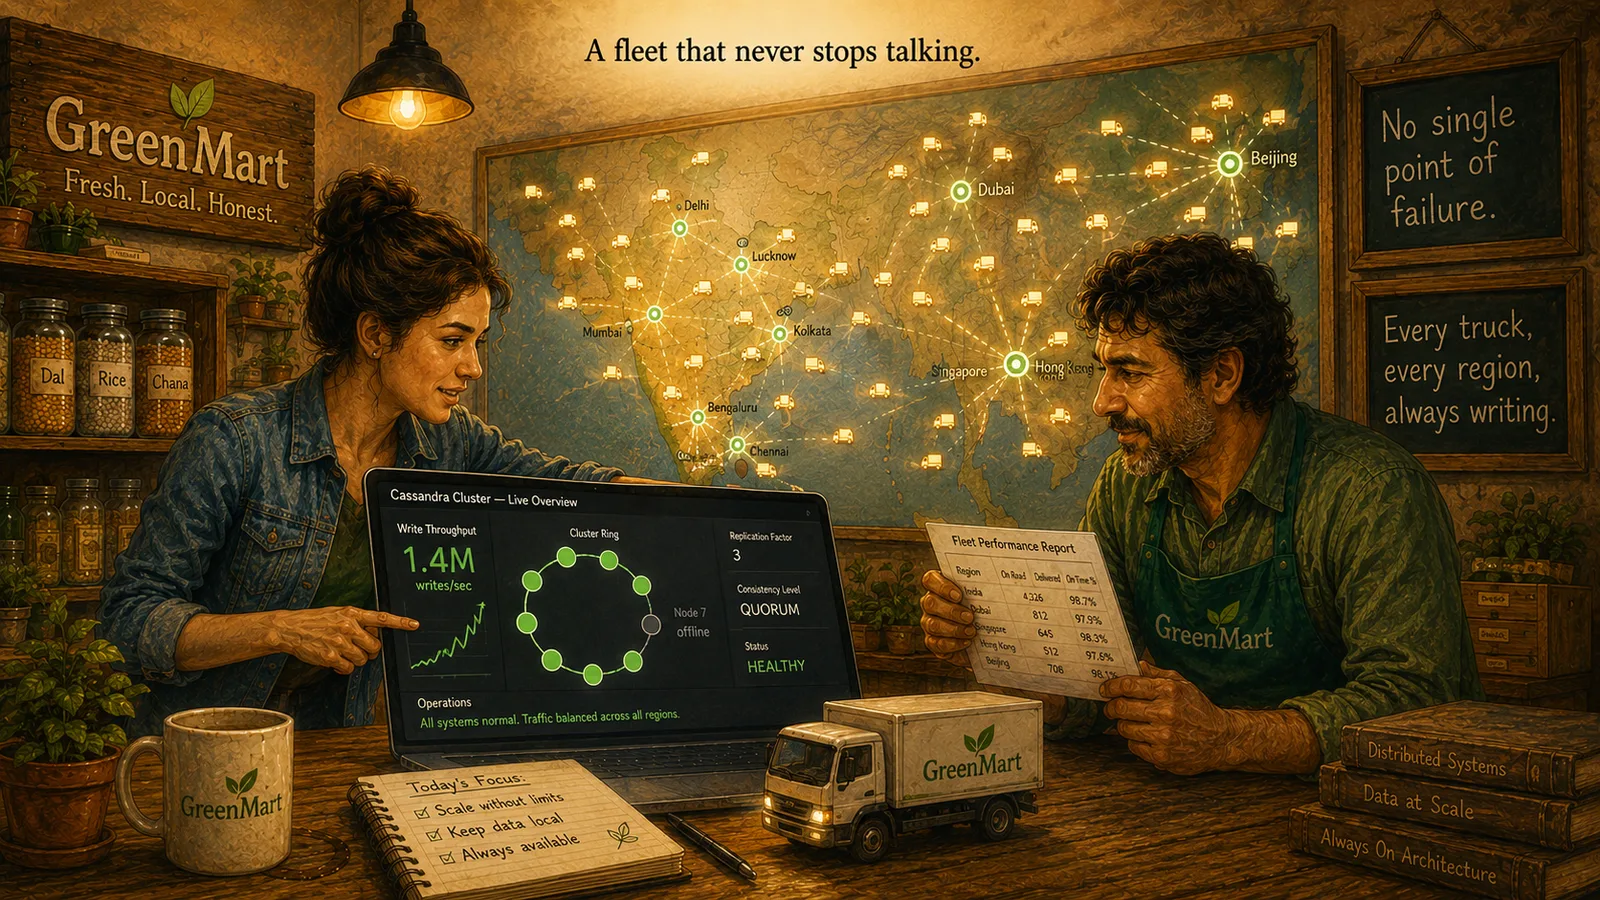
Mike looks at the live cluster dashboard Sarah pulled up earlier — the one shaped like a ring, with a handful of glowing dots connected in a circle, one dimmed grey. "Which one of these is the main server?" he asks.
Sarah has to explain that the question doesn't quite apply. There isn't one. Any of those dots can answer a request. Any of them can go dark, one at a time, without anyone declaring a new leader — because there was never a leader to begin with.
No main server at all? Then who's actually in charge?
Mike
One Server in Charge vs. Every Node an Equal
A ring, not a hierarchy
Every node owns a token range on a conceptual ring — there's no primary node and no leader election.
The partitioner maps keys to nodes
A hash function (Murmur3, by default) turns a partition key into a point on the ring — whichever node owns that range owns the row.
Gossip spreads cluster state
Nodes periodically exchange state with a few random peers — cluster-wide awareness with no central bulletin board.
Coordinator is a per-request role
Whichever node receives a client's request becomes its coordinator — routing, waiting for replicas, and replying — then goes back to being an equal.
The Ring, Gossip & Coordinator Nodes
A Cassandra cluster is a set of nodes — ordinary machines, each running the same Cassandra process, each holding a share of the cluster's total data. There's no primary node, no leader election, no single machine whose failure takes the whole system down. Every node is, structurally, an equal.
That equality is made real by the ring: conceptually, every node in the cluster is arranged in a circle, and each one owns a range of hashed values called a token range. A partitioner (a hash function — Cassandra's default is Murmur3) takes a row's partition key and hashes it to one specific point on that ring. Whichever node owns the token range containing that point is where the row actually lives.
So how does a node even know which requests belong to it, or whether the rest of the cluster is still healthy? Through gossip — literally the same idea as the word suggests. Every node periodically exchanges cluster-state information with a few random other nodes: who's up, who's down, how the token ranges are currently assigned. That state spreads across the whole cluster the way a rumor spreads through a room, node to node, with no central bulletin board anyone has to check. Within a few rounds of gossip, every node has a reasonably current picture of the entire cluster, without ever talking to a designated coordinator for that information.
One more role worth naming: when a client sends a request, it can hit any node in the cluster — that node becomes the coordinator for that one specific request. Its job is simple: figure out (using the same token-range math every node already knows) which node actually owns the data, forward the request there, wait for however many replicas the requested consistency level demands, and hand the result back. "Coordinator" isn't a fixed role assigned to one special machine — it's just whichever node happened to receive that particular request. The very next request might be coordinated by a completely different node.
Key Takeaway
There's no leader to fail. Gossip keeps every node's picture of the cluster current without a central authority, the ring's token ranges decide where data actually lives, and "coordinator" is a temporary job any node picks up for one request at a time — which is exactly how one dead node, like the dimmed dot on that dashboard, never becomes the whole system's single point of failure.
Why This Matters
This is the actual mechanism behind everything the rest of this Act depends on: how many copies of GreenMart's data exist and where (next chapter), how failures get handled gracefully (a later chapter), and how GreenMart can add capacity by simply adding more machines to the ring, not by provisioning a bigger single server.
GreenMart now knows why no single truck's data — or single node's failure — can take the fleet-tracking system down. What determines how many copies of that data exist, and how sure a read needs to be that it has the latest one, is exactly where the next chapter goes.