

In this chapter
We'll see how Cassandra absorbs a node failure without incident (tunable consistency, hinted handoff), what multi-datacenter deployment actually changes, why scaling is close to linear, and a direct roundup of the anti-patterns this whole Act was quietly built to avoid.
The Problem in Real Life
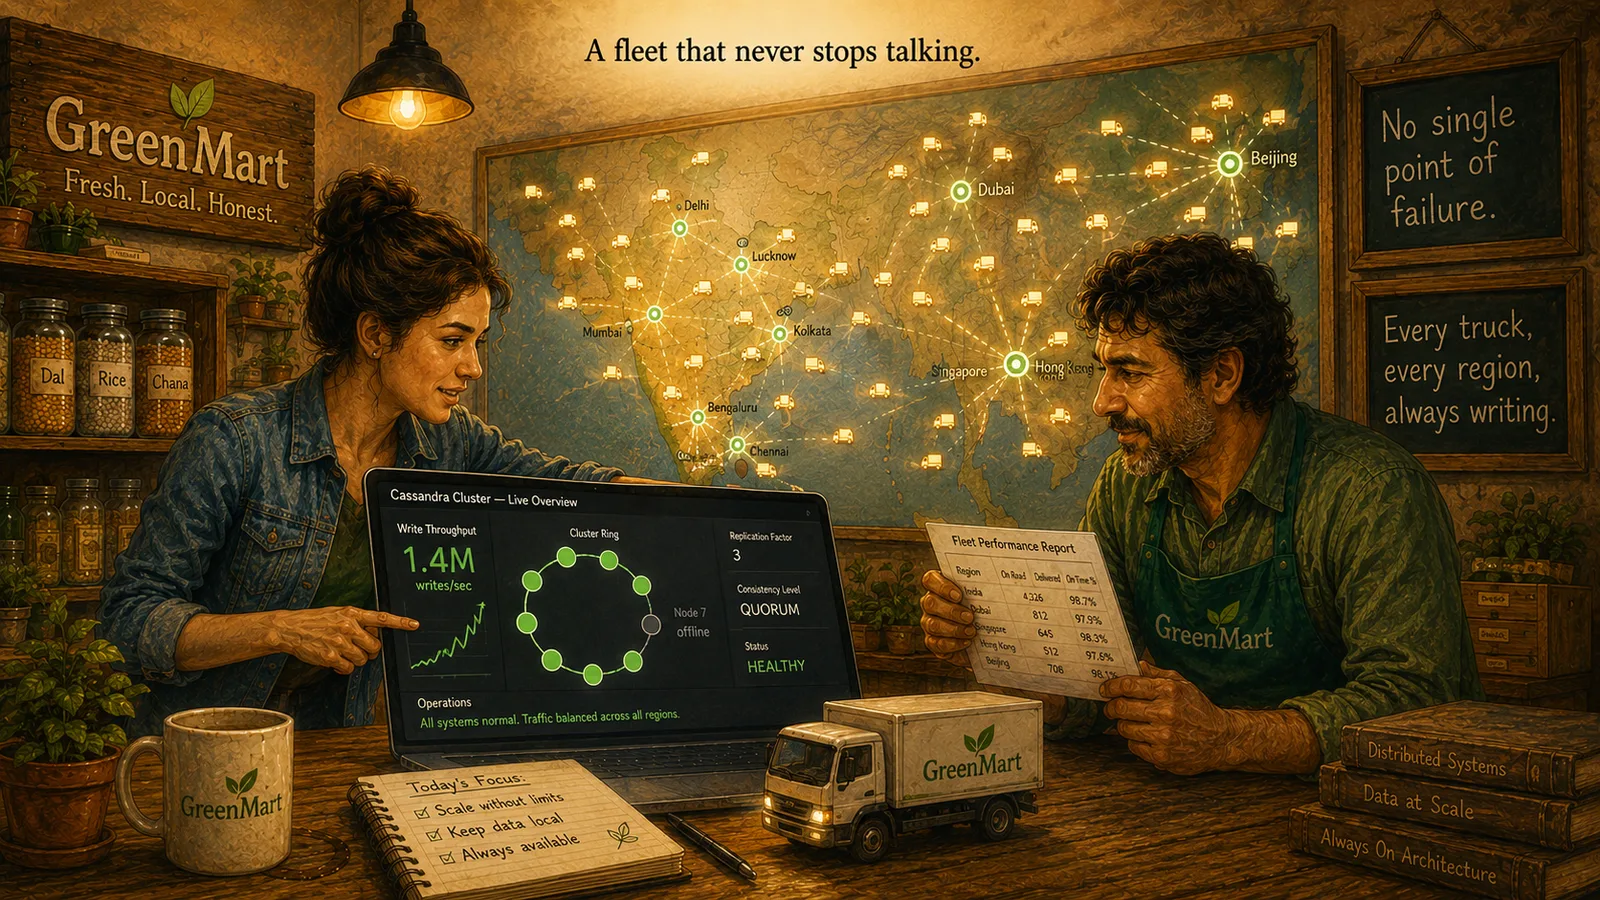
A node in GreenMart's cluster goes dark mid-shift — a hardware fault, nothing dramatic. Sarah watches the dashboard: no alarms, no dropped writes, no customer-facing error. Trucks keep pinging. Deliveries keep updating. The only sign anything happened is one dimmed dot on the ring.
Mike notices anyway, because he's learned to ask the right question by now.
So a node just died and... nothing happened? What actually caught that?
Mike
A Failure That Cascades vs. A Failure That's Just Absorbed
A dead node is absorbed, not an emergency
If the consistency level can still be met by the remaining replicas, writes and reads simply route around the failure.
Hinted handoff catches up automatically
A healthy replica temporarily holds writes meant for a down node, then replays them once it's back — no manual repair needed for a brief outage.
Multi-datacenter is one setting away
Replication strategy can specify replica counts per datacenter — local-latency reads and writes, still one logical cluster.
Scaling is near-linear, hot partitions aren't fixed by it
Adding a node redistributes data automatically — but a single overloaded partition key still needs its own fix, not more nodes.
Failure Handling & Multi-Datacenter Deployment
Three real, separate questions, the same pattern this course keeps returning to. What actually happens the moment a node goes down? What happens once GreenMart is running across more than one physical location? And what does it take to just add more capacity when the fleet keeps growing?
- On failure handling — what actually happens when a node goes down? If a write's consistency level can still be satisfied by the remaining healthy replicas (QUORUM with one of three replicas down is still achievable), the write and any read simply succeed, routed around the dead node entirely — this is the direct payoff of last chapter's tunable consistency. Hinted handoff goes further: a healthy replica can temporarily hold onto writes meant for the down node, then replay them once it's back — so a brief outage doesn't even require the slower
repairprocess to catch that node back up. Failure here isn't an emergency response; it's an expected, absorbed condition the system was built around from the start. - On multi-datacenter deployment — what changes once GreenMart runs in more than one place? A keyspace's replication strategy can specify how many replicas live in each datacenter separately — say, 3 copies in GreenMart's India datacenter, 2 in a Europe datacenter for the international routes this course's earlier Acts already introduced. Each datacenter can serve its own local reads and writes at local latency, while still being one logical, eventually-synchronized cluster — the same multi-region payoff DynamoDB's Global Tables promised, achieved here through Cassandra's own replication-strategy mechanism instead of a managed cloud feature.
- On scaling — what does growing the fleet actually require? Adding a new node to the ring is close to a linear operation: the new node takes over a share of the existing token ranges, and the cluster automatically redistributes data onto it — no downtime, no manual resharding plan. The one real limit this doesn't fix on its own is a hot partition — one partition key (a single mega-city with a disproportionate share of trucks, say) receiving far more traffic than the rest, becoming a bottleneck no amount of adding nodes elsewhere in the ring relieves. It's the exact same lesson Redis's hot keys and DynamoDB's hot partitions already taught, in a third product now — spreading load evenly across partition key values is still the real fix, not something scaling the cluster can substitute for.
A few real Cassandra anti-patterns, worth naming directly since this whole Act was really building toward avoiding them: using Cassandra like a relational database, reaching for secondary indexes and ad-hoc queries instead of query-driven modelling from the start; letting a single partition grow unbounded (an "always-append, never-rotate" partition key eventually becomes its own hot-partition problem); and using Cassandra for workloads that genuinely need multi-row transactions or complex joins, which it was never built to provide. Every one of these looks reasonable in isolation and only reveals itself as a mistake once real traffic and real data volume show up — the same honest pattern this course has named for every database it's taught.
Key Takeaway
A node failing here isn't an incident — it's an absorbed, expected condition, because tunable consistency, hinted handoff, and a ring built to redistribute automatically were all designed around failure happening, not around hoping it doesn't.
Why This Matters
This closes the loop this Act's very first chapter opened with: GreenMart wanted a database where one machine's failure was never the reason a truck's data didn't get logged. Everything in this chapter — absorbed node failure, multi-datacenter replication, near-linear scaling — is the fullest version of that promise actually being kept.
GreenMart's fleet-tracking system can now survive a dead node, run across regions, and grow by just adding machines. The checkpoint ahead asks Sarah — or you — to design GreenMart's actual fleet-tracking keyspace from scratch, with every one of this Act's lessons made on purpose.