

In this chapter
We'll meet append-heavy workloads, high-frequency writes, and time-based partitioning — why organizing storage by time keeps a time-range query fast no matter how much older data exists — plus an honest note on compression, a real technique this simulator doesn't physically implement.
The Problem in Real Life
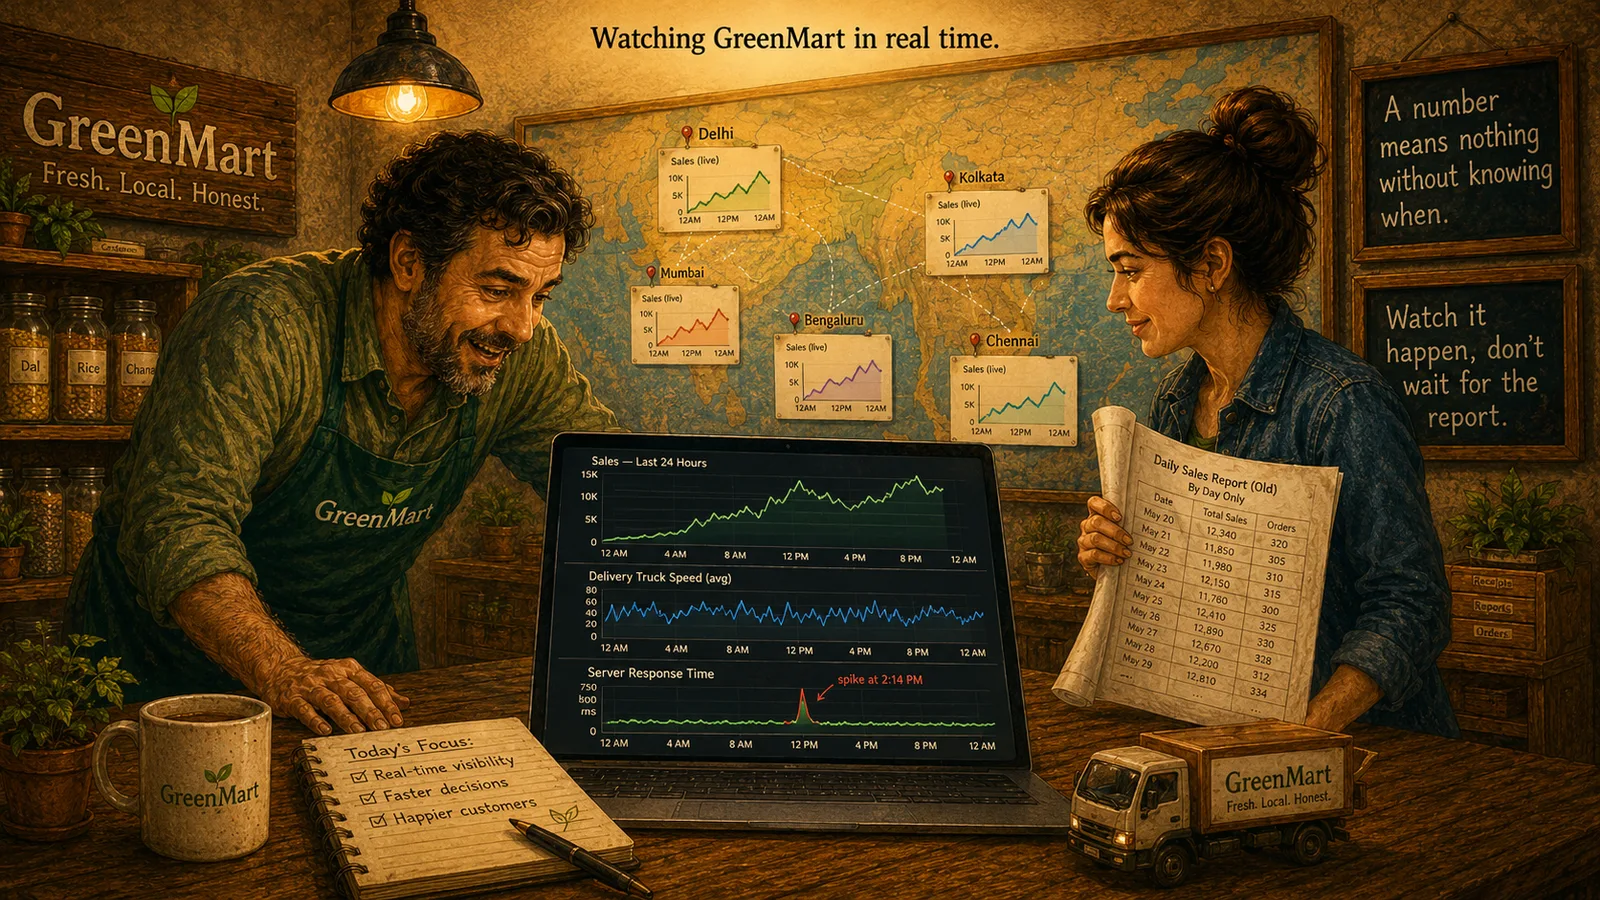
The same delivery fleet from GreenMart's Cassandra Act, now feeding Mike's new dashboard. Every truck, every few seconds, all day. Cassandra already proved it could absorb that volume. The question this chapter actually asks is different: once all of it's written, how does a dashboard read "the last hour" back out fast, out of what's already millions of points?
Writing fast was the old problem. Reading a time range back out fast is this one.
Sarah
Writes Scattered Everywhere vs. Writes Organized By Time
Append-heavy, almost never updated
A reading is a permanent fact about a moment — time-series workloads are overwhelmingly new writes, rarely edits.
High-frequency writes, from everywhere
A reading every few seconds, from every truck, all day — the real scale this chapter's mechanism has to sustain.
Time-based partitioning keeps reads fast
Data grouped by when it arrived — a time-range query only touches the partitions covering that range, never older data.
Compression is real, not simulated here
Consecutive readings compress well in production systems — this in-memory simulator demonstrates the query shape, not the physical technique.
High-Frequency Writes & Time-Based Partitioning
Time-series workloads are almost always append-heavy: overwhelmingly new writes, almost never updates to old data. A truck's speed at 9:00am doesn't get edited later — it's a fact about that moment, permanent the instant it's written. This is genuinely simpler than update-heavy workloads earlier Acts dealt with, and time-series databases lean into it hard.
High-frequency writes — a reading every few seconds, from every truck, all day — is the actual scale this chapter is about. The mechanism that makes reading a time range back out fast, even at that volume, is time-based partitioning: data physically grouped by the time it arrived, not by truck, not by region. A query for "the last hour" only has to touch the physical partition(s) covering that hour — it never has to scan through last month's data to find this morning's.
Two trucks, writing every minute, each tagged by which truck and which region. The query pulls back just the north region's readings — this is the shape of the actual production question a real system answers constantly: not "give me everything," but "give me this slice, for this time range," fast, no matter how much older data already exists.
INSERT truck.speed 42 truck=T1,region=north at +0mINSERT truck.speed 48 truck=T2,region=south at +0mINSERT truck.speed 55 truck=T1,region=north at +1mINSERT truck.speed 40 truck=T2,region=south at +1mQUERY truck.speed WHERE region=north
Two things worth being precise about, honestly. This simulator keeps everything in one in-memory array — it doesn't implement real time-based partitioning (physically splitting storage by time range) or real compression (time-series values are famously compressible, since consecutive readings from the same sensor are usually close to each other — a real production database exploits that heavily to keep storage costs sane at this volume). Both are genuine, important techniques in real systems like InfluxDB or TimescaleDB; this teaching tool demonstrates the query shape they enable, not the physical mechanism underneath.
What is real here: querying a specific time range, or a specific tag slice, stays exactly as fast whether there are four points or four million, because the simulator (like a real system) never has to touch data outside what the query actually asked for.
Key Takeaway
An append-heavy workload and time-based partitioning aren't separate facts about time-series databases — they're the same idea from two directions. Because old data is never edited, physically organizing storage by time (so a query only touches the time range it asked for) is both possible and enormously effective, in a way it wouldn't be if old rows kept changing underneath it.
Why This Matters
Every chapter left in this Act assumes writes keep arriving at real volume, constantly. Downsampling (next chapter) is really about what happens to all of this data once there's too much of it to look at point-by-point, even with fast time-range queries.
GreenMart's fleet can now write constantly, and a dashboard can still pull back exactly the time slice it needs, fast. A full day of that same data, one point at a time, is still too much to actually look at — turning a flood of points into a readable chart is exactly where the next chapter goes.