

In this chapter
We'll meet embeddings and embedding models as the real machinery behind vectors, and see cosine similarity, Euclidean distance, and dot product as three real, related ways to measure closeness — verified with actual numbers from the same query against a close match and a far one.
The Problem in Real Life
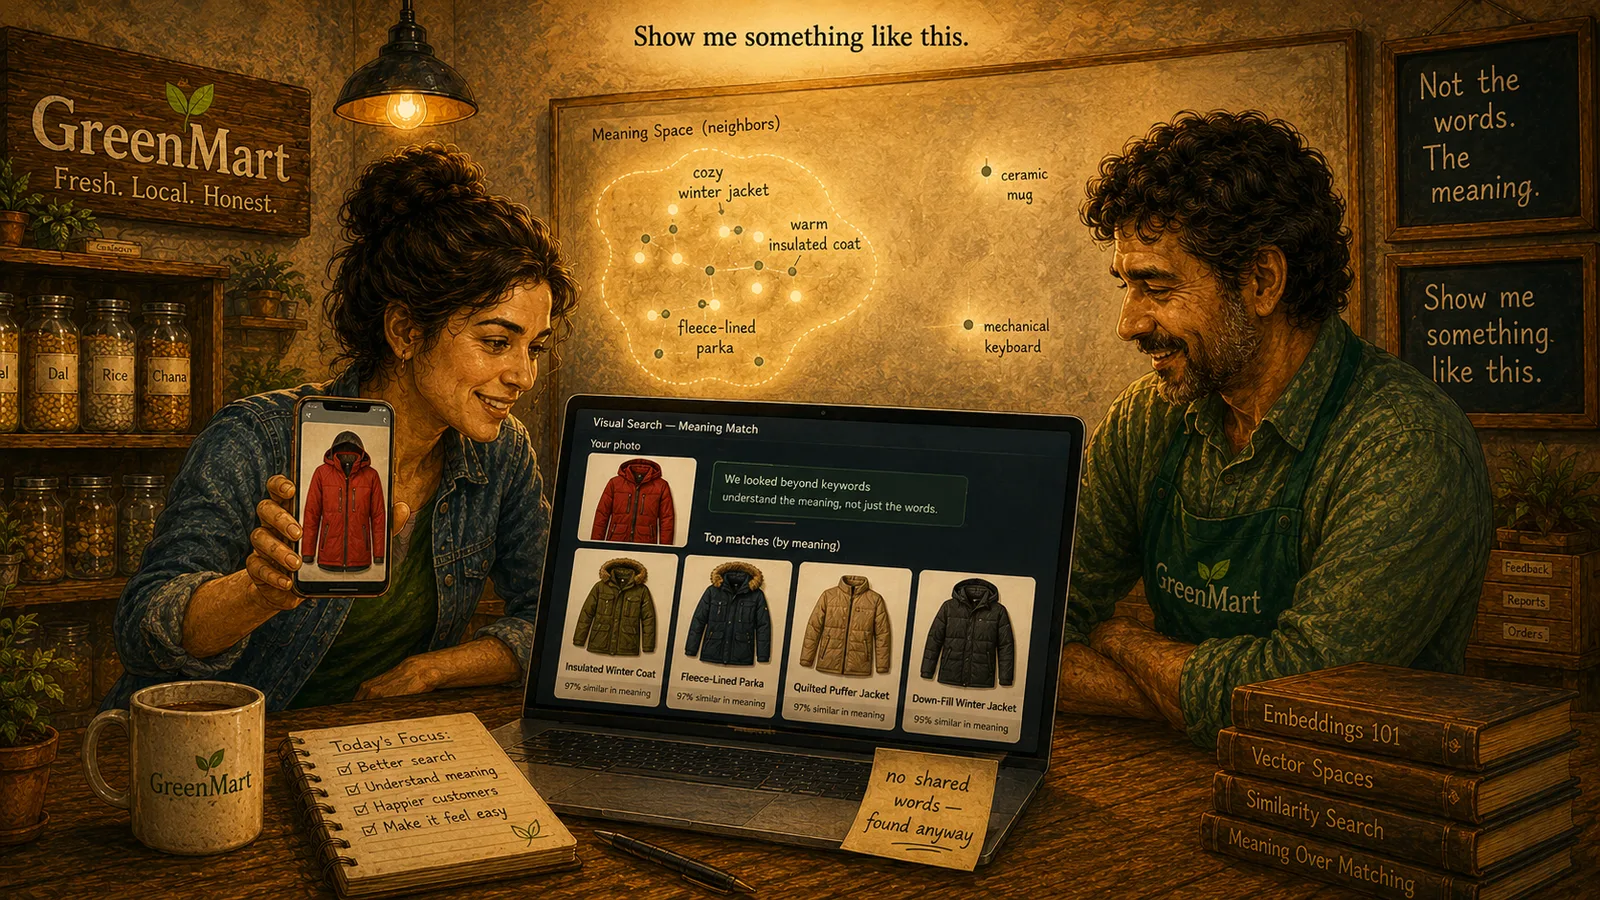
Mike wants the shopping assistant to work from a photo too — a customer holds up their phone, snaps a picture of a jacket they like, and GreenMart finds something close to it. "How does a photo turn into the same kind of search as typing a sentence?" he asks.
It doesn't, quite — this course's own Playground works on text, not raw images. But the real answer explains both: whatever the input is, an embedding model turns it into the exact same kind of thing — a vector — and everything downstream works identically from there.
A photo and a sentence end up as the same kind of thing?
Mike
Comparing Words vs. Comparing Meaning, Numerically
An embedding model turns input into a vector
Trained on enormous data, a real model like all-MiniLM-L6-v2 produces a real, 384-number vector for any text it's given.
Cosine similarity is the metric used here
Measures the angle between two vectors — verified: 0.6770 for a close match, 0.0739 for a distant one.
Dot product equals cosine similarity, here
For normalized (length-1) vectors, a simple multiply-and-sum gives the exact same number as the angle-based metric.
Any input type, the same mechanism
A photo and a sentence use different embedding models, but both produce a vector, compared the exact same way.
Embeddings & Semantic Similarity
An embedding is the actual vector a model produces for a given piece of input. "How text becomes vectors" is genuinely a machine-learning model's job, not a simple formula — a real embedding model (this course's own Playground uses all-MiniLM-L6-v2, a real, open model) has already been trained on enormous amounts of text, learning to place meanings near each other in a high-dimensional space. Running a sentence through it produces one real vector: 384 numbers, every single time, for this course's specific model.
Distance metrics are how "close" actually gets measured between two of these vectors. Cosine similarity measures the angle between two vectors — ignoring their length, purely their direction — and is the metric this course's own Playground actually uses. Euclidean distance measures straight-line distance between two points instead. Dot product is a plain multiply-and-sum of two vectors' numbers — and for vectors that are already normalized to length 1 (as this course's own model's output is), the dot product and cosine similarity become mathematically the exact same number, which is exactly why the actual engine computes cosine similarity via a simple dot product, not a more expensive angle calculation.
Every one of these becomes a real, 384-number vector. Cosine similarity (query vs. coat): 0.6770 — genuinely close. Cosine similarity (query vs. keyboard): 0.0739 — genuinely far. Euclidean distance tells the same real story from the other direction: 0.8037 (query to coat, a short distance) versus 1.3609 (query to keyboard, a longer one). Higher cosine similarity and lower Euclidean distance both mean "closer in meaning" — just measured differently.
cozy jacket for cold weatherInsulated Winter Coat — a warm, padded coat built for freezing temperatures.Mechanical Keyboard — a tactile keyboard with backlit keys.
384 is this specific model's real output size — a different embedding model would produce a different number of dimensions, but the same underlying idea.
This is also the honest answer to Mike's photo question: a real production system uses a different embedding model for images than for text — one trained specifically to place a photo's visual meaning into a vector space, ideally one compatible with the text model's own space, so a photo and a sentence describing something similar end up close together. This course's Playground only runs the text model, but the mechanism — input goes in, a real trained model produces a vector, distance between vectors measures similarity — is identical either way.
This is where the Act's core realization stops being an abstract line and becomes something with real, checkable numbers behind it: a traditional database's WHERE clause, and even Act 7's fuzzy full-text search, are both fundamentally asking "does this match?" A vector system asks a genuinely different, numerical question — "how close is this, mathematically, in a space built to represent meaning?" — and answers it with a real, computed number, not a boolean.
Key Takeaway
Traditional databases search for matching data; vector systems search for data that is mathematically close in meaning. An embedding model is what makes that a real, computable question — turning any input into a vector, then measuring the real distance between vectors with cosine similarity, Euclidean distance, or a dot product, verified here with actual numbers: 0.68 close, 0.07 far.
Why This Matters
Every remaining chapter in this Act assumes this exact mechanism — a real embedding model producing a real vector, a real distance metric comparing it to others. Approximate nearest-neighbor search, next chapter, is entirely about doing this same comparison fast, at a scale where comparing against every single vector one by one stops being practical.
GreenMart now has the actual mechanism behind meaning-based search, with real numbers to check it against. Comparing one query against five products is instant — comparing it against five million is a genuinely different problem, and exactly where the next chapter goes.