

In this chapter
We'll meet ten real-world database comparison pairs and see that each resolves the same way — not with a universal winner, but by naming the real workload's requirements first.
The Problem in Real Life
Sarah steps back from GreenMart's own fleet-and-order requirement for a moment. The reasoning she just walked through isn't specific to this one decision — it's the same reasoning behind every real database choice, anywhere.
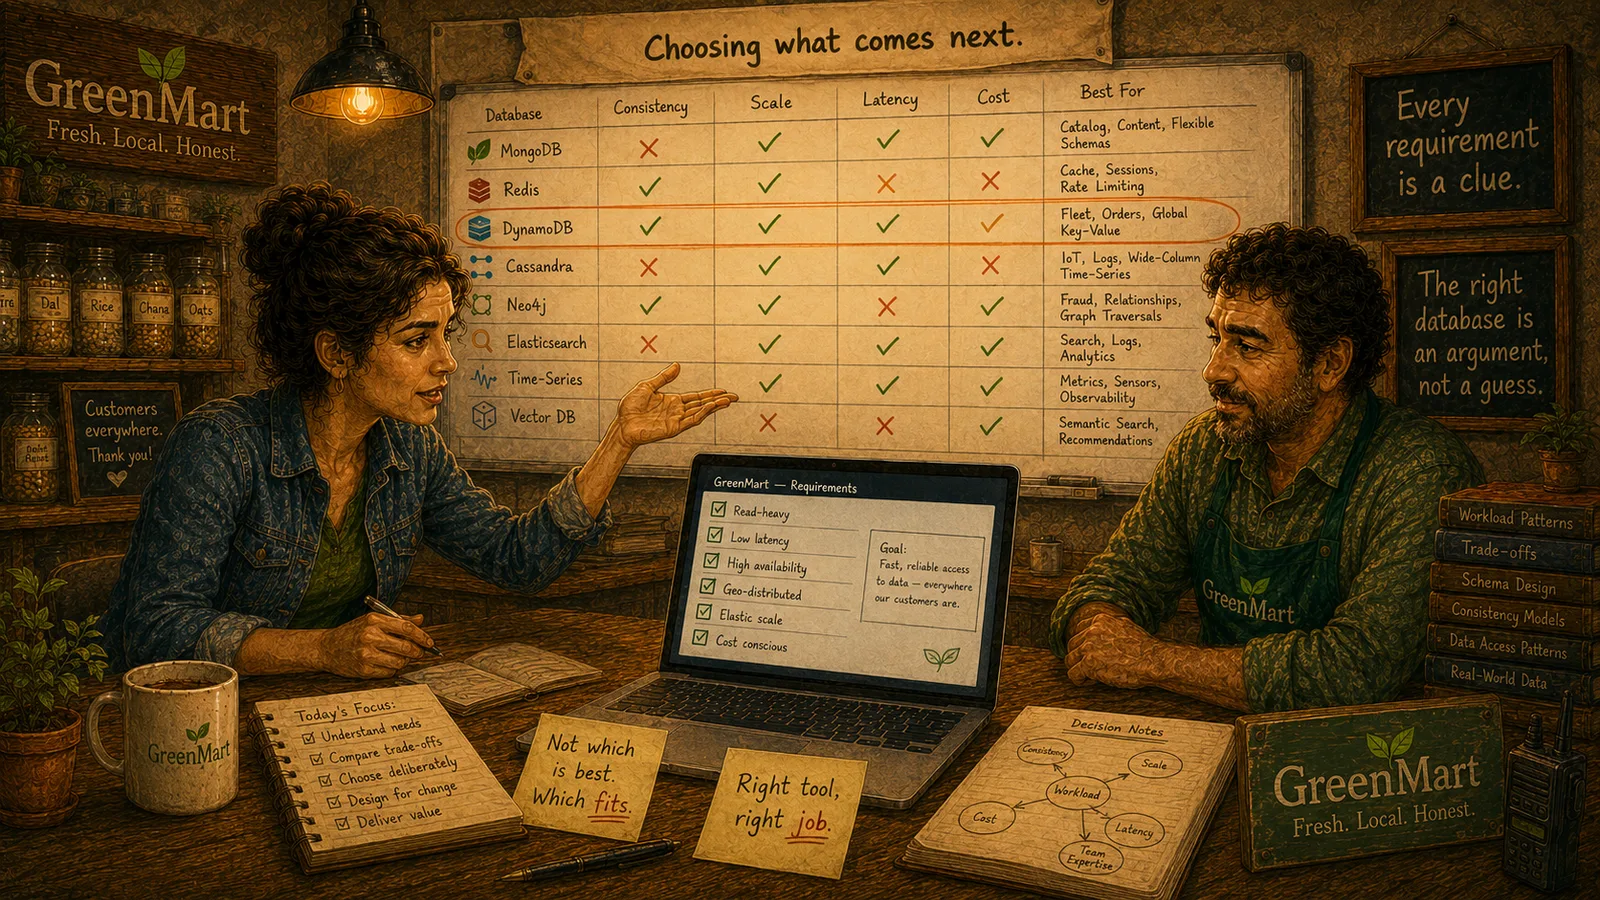
She sketches a wider table on the whiteboard: not just GreenMart's own problem, but ten real, common ones — the same kind of "which one do I use" question, asked by real teams, over and over.
This isn't just our decision. It's the same decision, over and over, everywhere.
Sarah
The Same Question, Asked Ten Different Ways
No pair has a universal winner
Every comparison in this chapter resolves differently depending on the real, specific workload asking the question.
Ten pairs, one repeated pattern
Each comparison is really the same workload-analysis question this Act has already taught, asked about a different pair of technologies.
Real-World Comparisons
Every one of these ten pairs is really the same question this whole Act has been teaching: what does the real workload need, and which side of the pair actually gives it that? None of them have one universally correct answer — each depends on the exact requirements the last five chapters taught how to name.
- MongoDB vs. DynamoDB — both are real, capable NoSQL databases, and the honest difference isn't "NoSQL vs. NoSQL," it's flexibility vs. scale ceiling. MongoDB's document model (Act 2) tolerates evolving, moderately-varied shapes gracefully; DynamoDB (Act 4) is built for a stricter access-pattern discipline in exchange for a genuinely higher, more predictable scale ceiling. A catalog that changes shape often leans MongoDB; a fleet of vehicles at massive, predictable scale leans DynamoDB — GreenMart's own real choice, from the chapters just covered.
- Cassandra vs. DynamoDB — both scale to enormous write volume, and the real difference is who runs it and how the ring is controlled. Cassandra (Act 5) is commonly self-managed, giving GreenMart direct control over the ring and consistency levels at the cost of real operational work; DynamoDB is fully managed, trading some of that control for far less day-to-day operational burden — exactly the managed-vs-self-managed question from two chapters ago.
- Elasticsearch vs. a database's own search — a database query answers "does this row match," exactly; Elasticsearch (Act 7) answers "which results are most relevant," approximately and ranked. A user typing a slightly misspelled product name needs Elasticsearch's fuzzy, ranked matching; an internal report pulling exact records by ID needs nothing more than the database it already lives in.
- One database vs. multiple databases — the polyglot-persistence question from the previous chapter, restated as its own real comparison: sometimes the honest answer to "which database" is "more than one," each doing the one job it's actually strong at, accepted as real, deliberate operational complexity rather than avoided out of a false sense of simplicity.
| Comparison | The Real Question Being Asked | Leans Toward the First Option When... |
|---|---|---|
| PostgreSQL vs. MongoDB | Fixed, well-understood schema vs. evolving, flexible shape | The data's shape is stable and relationships matter more than flexibility |
| MongoDB vs. DynamoDB | Schema flexibility vs. a higher, stricter-discipline scale ceiling | The catalog's shape changes often and scale stays moderate |
| Redis vs. a general-purpose database | Sub-millisecond in-memory speed vs. being the durable source of truth | The data is disposable, or backed by a real database elsewhere |
| Cassandra vs. DynamoDB | Self-managed ring control vs. fully managed operational simplicity | The team wants direct control over consistency levels and topology |
| Neo4j vs. PostgreSQL | Deep, multi-hop relationship traversal vs. a handful of simple joins | The real question is about paths and connections, several hops deep |
| Elasticsearch vs. a database's own search | Ranked, fuzzy relevance vs. exact-match lookup | Users type real, imperfect search terms expecting ranked results |
| Time-series DB vs. PostgreSQL | High-frequency writes with time-based rollups vs. general-purpose storage | Data arrives constantly, timestamped, and gets downsampled over time |
| Vector DB vs. PostgreSQL + pgvector | A dedicated engine at real embedding scale vs. a bolt-on for smaller scale | Semantic search is a core, high-volume feature, not an occasional one |
| Firestore vs. a traditional backend | Built-in real-time sync vs. building that sync by hand | Multiple clients need to see the same live data update instantly |
| One database vs. multiple databases | One tool stretched across two shapes vs. two tools, each doing one job | The workload is genuinely two different shapes wearing one name |
None of these ten rows has a single right answer written in stone — each one resolves the same way GreenMart's own fleet-and-order requirement just did: by naming the real workload first, then choosing the side that actually fits it.
The remaining six pairs follow the exact same pattern — a real trade-off, not a universal winner, resolved by the same workload-analysis questions this Act has already taught.
Key Takeaway
Ten different comparisons, one repeated lesson: there's no universal "better" database in any of these pairs — only a better fit for a specific, honestly-named workload, the exact skill the last five chapters just practiced.
Why This Matters
Recognizing that GreenMart's own fleet-and-order decision is really the same shape of question as "MongoDB or DynamoDB" or "one database or several" is what turns this course's thirteen separate Acts into one transferable skill, usable on the next decision this course never specifically covered.
GreenMart now has ten real, common comparisons to recognize the next time a similar choice comes up — each resolved the same way, by the workload's own real requirements. The next chapter turns all of this into one repeatable framework, applied live to GreenMart's own fleet-and-order requirement, start to finish.