

In this chapter
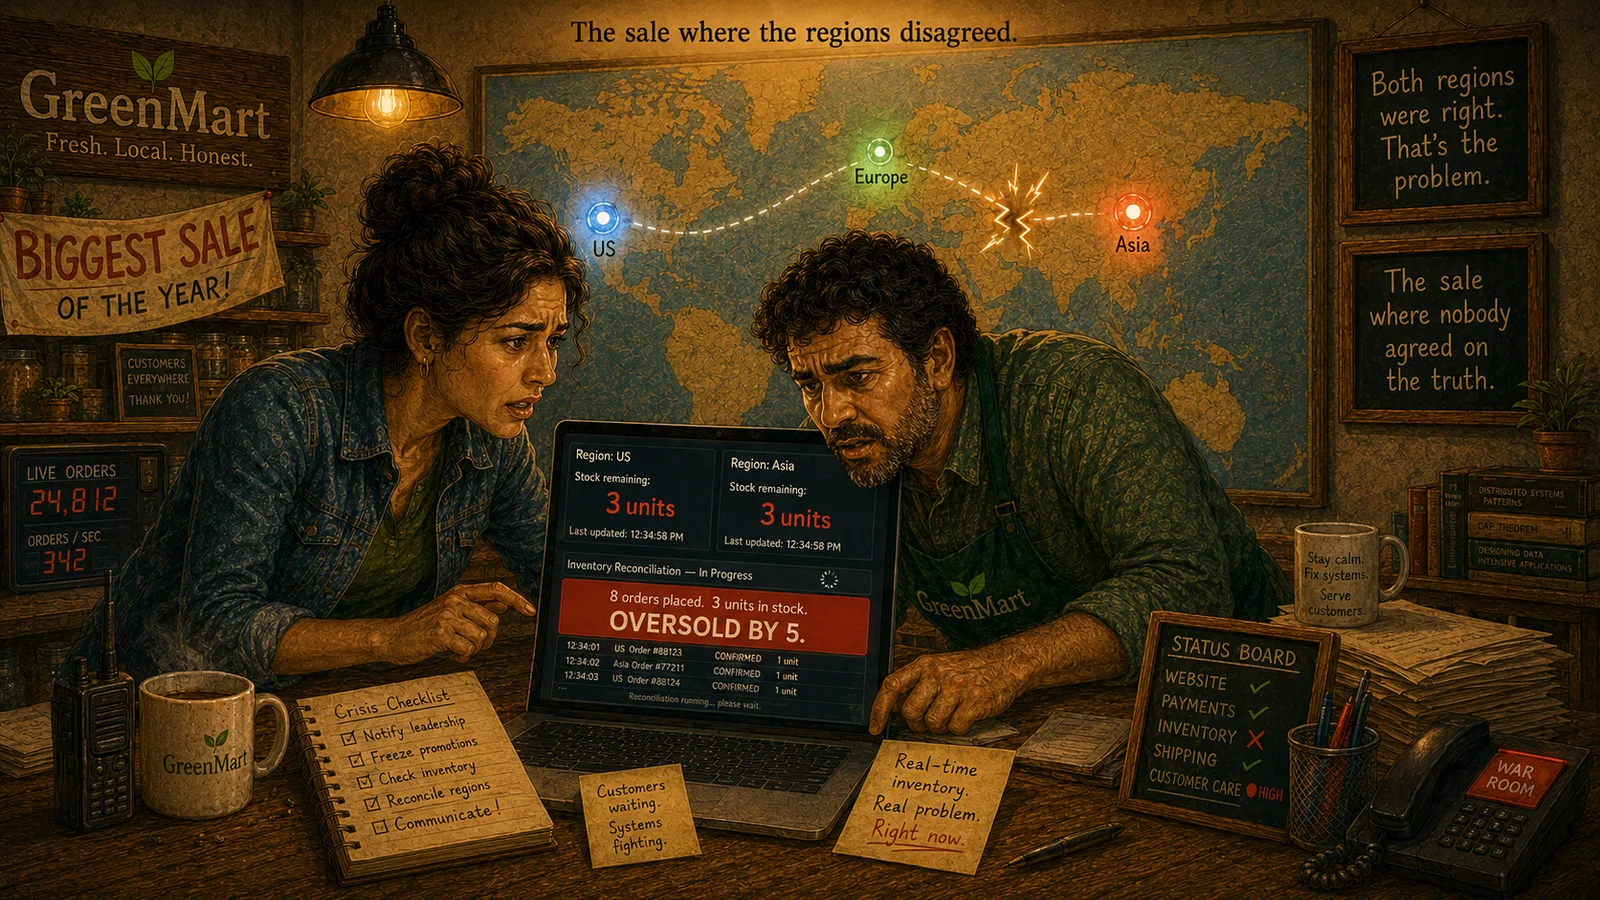
We'll name exactly what broke — a real network partition — and the real, unavoidable choice it forces: the CAP theorem's Consistency vs. Availability trade-off, contrasted against a banking system's own, differently-made version of the same choice, landing this Act's own core realization directly on GreenMart's own incident.
The Problem in Real Life
Sarah finally has the vocabulary for what happened, and it changes how she explains it to Mike: not "a bug," not "bad luck" — a real, well-known category of failure with a name, and a real, well-known trade-off underneath it that every distributed system eventually has to make.
What broke between the two regions has a name: a network partition. What each region chose to do about it — keep serving customers anyway — has a name too, and it wasn't the only option.
It's not that we did something wrong. It's that this exact choice was always going to have to be made eventually.
Sarah
Two Genuinely Different Choices, Once the Link Breaks
A network partition is real and common
Two parts of a system that can no longer talk to each other, while both are still up — not rare, not exotic.
CAP is a choice during a partition, specifically
Not "pick two of three" always — the real, forced choice is Consistency vs. Availability, once a partition is actually happening.
GreenMart chose Availability, silently
Both regions kept selling rather than refuse real customers — the correct-sounding choice that directly caused the oversell.
The same choice, made differently elsewhere
A banking transfer usually favors Consistency instead — neither answer is universally right, the real cost of being wrong differs.
Network Partitions & the CAP Theorem
A network partition is exactly what GreenMart lived through in the last chapter: two parts of a distributed system that can no longer communicate with each other, while both are still up and still able to talk to their own customers. This is not rare or exotic — real networks genuinely fail this way, regularly, at real scale, which is exactly why any system spread across more than one place has to have a real answer for it, not just hope it never happens.
The Moment a Partition Happens
Before
US region and Asia region, one link, both sides agree: 3 units left
During the partition
US region: keeps serving, sells against its own 3-unit view. Asia region: keeps serving, sells against its own 3-unit view.
The real fork
Keep answering (favor Availability) — or refuse until reconnected (favor Consistency)
The CAP theorem describes the real choice a system faces the instant a partition like that actually happens. Once two parts of a system genuinely can't talk to each other, each side has exactly two honest options: keep answering requests, possibly giving an answer that's no longer confirmed to match the other side (favoring Availability), or refuse to answer until it can confirm it's not going to contradict the other side (favoring Consistency). It cannot do both at once — that's the actual, precise content of the theorem, not "pick two of three forever." Partition tolerance isn't really a choice for a real distributed system; partitions happen. The real decision CAP describes is Consistency versus Availability, specifically during one.
GreenMart's two regions each chose Availability: keep selling, don't refuse a real customer's real order just because the other region is currently unreachable. That's not automatically the wrong choice — it's a real, common, defensible one for a lot of workloads. It's also exactly why the oversell happened: choosing Availability during a partition means accepting that, for a while, the system's answers might not be fully consistent with each other. GreenMart got the second half of that trade without having consciously decided on the first half.
Worth seeing this same real choice made differently, somewhere else: a banking system handling a funds transfer, mid-partition, usually makes the opposite call — it refuses to process a withdrawal it can't confirm against the account's other, currently-unreachable replica, favoring Consistency even at the cost of a frustrated customer staring at a temporarily unavailable ATM. Neither choice is universally right. A stale stock count is a minor, correctable inconvenience; a wrongly-approved double withdrawal is real money, gone. The same theorem, the same forced choice, two genuinely different, both-defensible answers — because the actual cost of being wrong is different in each case.
Key Takeaway
Distributed databases aren't difficult because storing data is difficult. They're difficult because machines fail independently while the application still expects one coherent system. CAP names the exact, unavoidable choice that failure forces — Consistency or Availability, the moment two parts of a system genuinely can't confirm they still agree — and GreenMart's incident is that choice, made silently, with real consequences.
Why This Matters
Every remaining chapter in this Act is really about the machinery underneath this one choice — how many copies have to agree before an answer counts as trustworthy, how a system decides who's in charge once the network heals, and how GreenMart can make this trade-off on purpose next time, instead of discovering it happened after the fact.
GreenMart now has real names for what happened and why — a network partition, and the Consistency-vs-Availability choice each region silently made during it. This same trade-off shows up constantly, not only during a dramatic outage — exactly where the next chapter goes.