

In this chapter
We'll turn thirteen Acts of database knowledge into one repeatable, four-step decision framework, applied live to GreenMart's fleet-and-order requirement — concluding with a real, defensible answer and the reasoning behind it.
The Problem in Real Life
Every fact is on the table now: the shape, the promises, the scale, the team, the risk, and ten real comparisons showing this same reasoning play out elsewhere. Mike asks the question that's been waiting since the first chapter of this Act.
Sarah doesn't reach for a name yet, even now. She reaches for the requirements sheet she's been building since chapter one, and turns it into a real, repeatable decision.
Okay. You've told me everything about the problem. Now which database?
Mike
"Which Database Is Best?" vs. "Which Database Fits This?"
Four repeatable steps, not a guess
Write the requirements down, score the real candidates, let the requirements decide, and state the reason out loud.
The real skill is the reason, not the answer
"DynamoDB" alone isn't the lesson — being able to say precisely why, against named requirements, is.
Building a Decision Framework
This course's real, final lesson isn't a longer list of databases — it's a repeatable process for turning a named set of requirements into a real, defensible decision. Four real steps, applied live to GreenMart's own fleet-and-order requirement.
- Step 1 — write the requirements down, precisely. Not from memory, from the last five chapters: mostly-flat data, a real read/write mix looked up by known keys; real transaction needs around dispatch, strong consistency preferred with honest tolerance for a brief reconciliation window, high availability, low worldwide latency; real scale, high velocity on location updates, moderate variety, genuine multi-country geographic spread; a team that already knows DynamoDB, wanting low operational overhead during the expansion; acceptable lock-in, no unusual compliance burden, real backup/recovery and failure tolerance already proven, real growth headroom, and — checked honestly — one coherent workload, not two disguised as one.
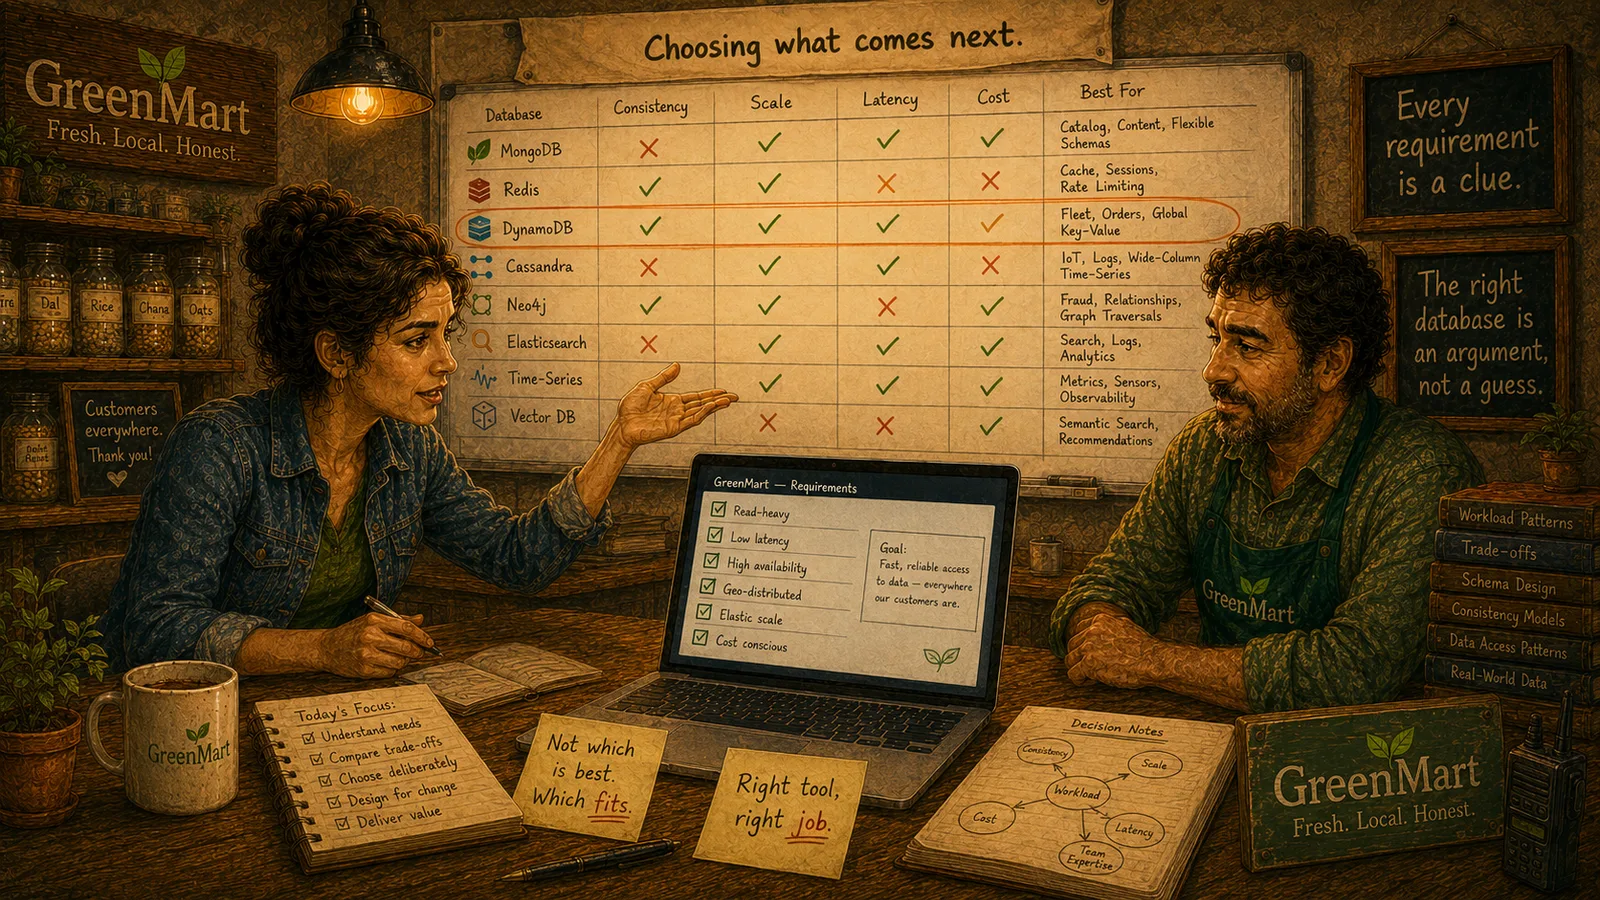
- Step 2 — score the real, serious candidates against those requirements, not against a popularity contest. Not every database this course covered is even a serious candidate here — Neo4j's deep traversal strength and Elasticsearch's ranked relevance both solve problems GreenMart's fleet-and-order requirement doesn't actually have. The real candidates worth scoring are the ones built for scale, low-latency, geographically-distributed key-based access: DynamoDB and Cassandra, chiefly.
- Step 3 — let the requirements decide, not a preference. DynamoDB: strong consistency options, proven multi-region scale via Global Tables (Act 4), low predictable latency, and — the deciding factor from two chapters ago — a managed service the team already runs confidently, keeping operational complexity down during a period the team is also busy shipping the expansion itself. Cassandra: comparable raw scale, but self-managed, meaning real additional operational work the team would be taking on for a workload that doesn't actually need Cassandra's specific write-throughput ceiling more than DynamoDB's.
- Step 4 — state the decision, and the real reason, out loud. Not "we're using DynamoDB because it's what we know" — the honest, complete version: "DynamoDB, because the requirements point to managed multi-region scale with predictable latency, the team already operates it confidently, and nothing about this workload's shape needs Cassandra's specific strengths enough to justify the added operational cost of running it ourselves." That sentence is the real skill this whole Act, and this whole course, was built to teach.
| Database | Consistency | Scale | Latency | Cost/Ops Fit | Verdict |
|---|---|---|---|---|---|
| MongoDB | Good | Good | Good | Weaker fit — not the team's current scale strength | Not chosen — flexibility isn't the binding constraint here |
| Redis | Good | Good | Excellent | Weak fit — not a durable source of truth | Not chosen — this is the source of truth, not a cache |
| DynamoDB | Good | Excellent | Excellent | Excellent — managed, team already runs it | Chosen |
| Cassandra | Weaker | Excellent | Good | Weaker fit — real added self-managed operational cost | Not chosen — no requirement justifies the extra operational load |
| Neo4j | Good | Weaker | Weaker | Weak fit — wrong shape of problem entirely | Not chosen — no deep relationship-traversal need here |
This is the same decision matrix GreenMart sketched on the whiteboard — scored honestly against the real requirements gathered in the last five chapters, not against which database sounds most impressive.
This isn't a special case. It's the same four steps for every future decision this course never specifically covered — write the real requirements down, score the real candidates against them, let the requirements decide, and be able to say the real reason out loud.
Key Takeaway
A database gets chosen well the same way every time: name the real requirements first, score the real candidates against them honestly, and be able to state the reason in one real sentence — not "it's what we know," but "here's what the workload needed, and here's which option actually gave it that."
Why This Matters
This is the whole course's real, final payoff: not memorizing which database does what, but a repeatable process for answering "which database, and why" on a problem this course never specifically taught — the actual skill every earlier Act was quietly building toward.
GreenMart now has both the answer for this specific fleet-and-order requirement — DynamoDB, for real, stated reasons — and the repeatable process that produced it. The checkpoint ahead asks Sarah — or you — to run that exact same process, start to finish, on GreenMart's own next real expansion.