

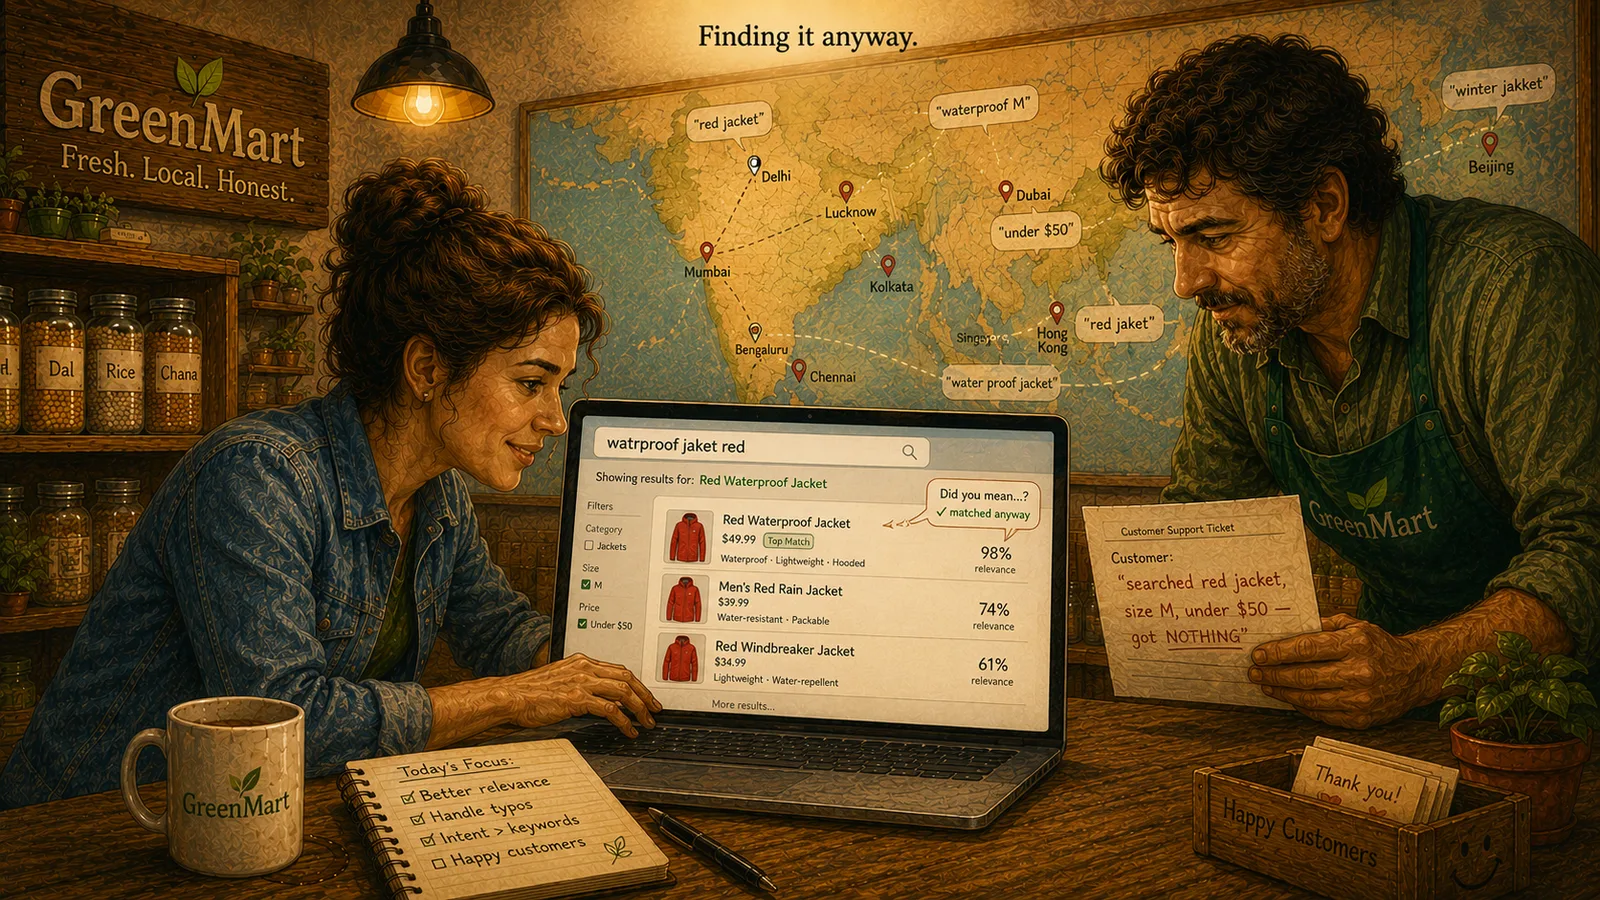
In this chapter
We'll meet relevance, scoring, and ranking — why a search engine returns imperfect matches in a deliberate order — and see honestly which query types (fuzzy, autocomplete) this course's real Search Playground supports versus which ones (boolean, phrase) are real production concepts its simple query box doesn't expose.
The Problem in Real Life
Sarah searches "wireless keyboard." Two products come back: the Mechanical Keyboard and the Wireless Noise-Cancelling Headphones. Neither one is actually a wireless keyboard — GreenMart doesn't sell one. But one of these two answers is clearly the better guess.
The search engine seems to know that too. It doesn't just return both — it puts one first.
Neither one's actually right. How does it know which wrong answer is more right?
Mike
"Does It Match?" vs. "How Well Does It Match?"
Relevance is a question of degree
Not "does it match," but "how good a match is this" — real queries usually return several imperfect answers, not one perfect one.
Scoring turns relevance into a number
A real, computable value a search engine can sort by — verified: 4.41 vs. 1.92 for two genuinely different matches.
Fuzzy search and autocomplete are real here
Typo tolerance and prefix matching are genuinely demonstrated, default-on behavior in this course's own Search Playground.
Boolean and phrase queries are honest gaps
Real production concepts (AND/OR, exact phrase matching) this Playground's simple query box doesn't expose special syntax for — confirmed directly.
Relevance, Scoring & Query Types
This is the real job a search engine is doing, underneath everything covered so far. Tokenization and the inverted index answer a yes-or-no question: does a document contain this token, or not? But real queries usually match several documents to different degrees — one matching every word, another matching only one — and "which one do I show first" is a genuinely harder question than "does it match at all."
Relevance is the concept: how good a match is this document, really, for this query? Scoring is how that gets turned into an actual number a computer can sort by. Ranking is sorting the results by that score, best match first.
Run against GreenMart's catalog, this real query returns both the Mechanical Keyboard and the Wireless Noise-Cancelling Headphones — neither one matches both words, but each matches one. Verified, real scores: the Mechanical Keyboard scores 4.41, the Headphones score 1.92. Both are real matches. Neither is a perfect one. The engine ranks the Keyboard first, not because it's correct, but because its score says it's the closer of the two imperfect answers.
wireless keyboard
This is genuine output from the real engine behind this course's Search Playground — not an invented example. Run it yourself and check the score numbers in the results.
This is also where real search engines offer different query types, each shaped for a different kind of question. Fuzzy search — already core to everything this Act has shown so far — tolerates small typos by edit distance. Autocomplete (built on prefix matching) finds documents whose tokens start with what's typed so far, which is exactly why typing "mech" already finds "Mechanical Keyboard" before the word is even finished. Both of these are real, demonstrated, default-on behavior in this course's own Search Playground.
Boolean queries (combining terms with AND/OR/NOT — "waterproof AND jacket, NOT insulated") and phrase queries (matching an exact sequence of words together, like "noise cancelling" as one unit rather than two separate tokens) are just as real and common in production search engines — but this course's Search Playground keeps its query box deliberately simple plain text, without a special syntax for either. Typing "wireless keyboard" with quotes, or wireless AND keyboard literally, doesn't change how this specific engine behaves — both quotes and the word "AND" just become more tokens to fuzzy-match, confirmed directly. A real production system like Elasticsearch supports both as genuine, distinct query types; worth knowing they exist, honestly separate from what this particular Playground's simple query box exposes.
Key Takeaway
A search engine isn't trying to answer "does this row match?" — it's trying to answer "which results are most relevant?" Two genuinely different, imperfect matches aren't a failure to resolve; ranking them by score, best guess first, is the actual point.
Why This Matters
Every real search a customer runs against GreenMart's catalog returns some kind of imperfect match more often than a single perfect one — relevance and ranking are what make that useful instead of confusing. Faceted search and filtering, next chapter, are the tools for narrowing a ranked list down further once it's already sorted by how good a match it is.
GreenMart now understands why search results come back in a specific order, not just as a matching set. A big catalog with hundreds of ranked results is still a lot to look through by hand, though — narrowing it down on purpose is exactly where the next chapter goes.